Compilation Pipeline
The five stages, what each reads and writes, and how caching works.
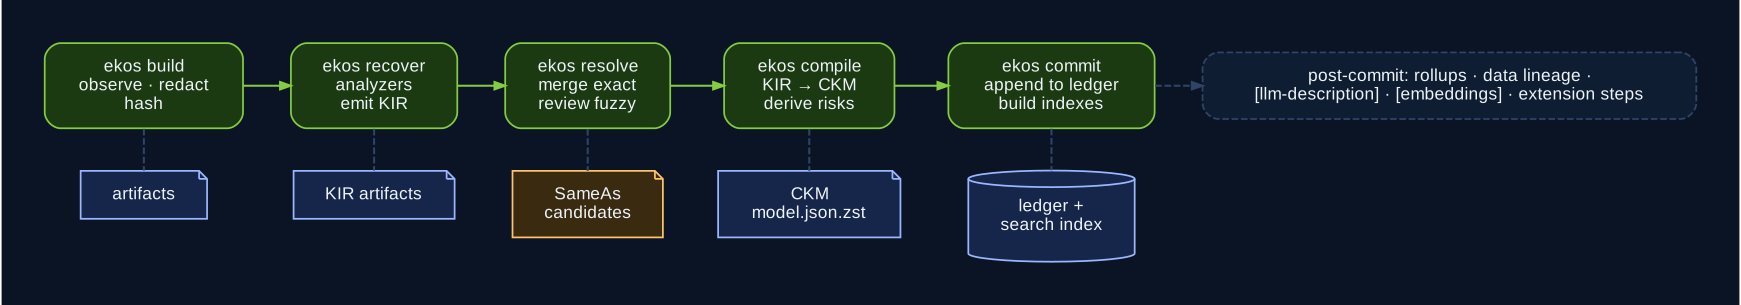
| Stage | Reads | Writes | Notes |
|---|---|---|---|
build |
[[sources]] / observe paths; [[databases]] |
observation artifacts; File objects; live catalog artifacts |
redaction runs here; fingerprint cache skips unchanged trees; live databases are read once per build outside that cache, and a failed read fails the build |
recover |
observation artifacts | KIR knowledge artifacts | analyzers are CompilerPasses scheduled by dependency; --parallel |
resolve |
KIR | identity decisions | exact merges; fuzzy → unconfirmed SameAs only when names agree word for word; live and structurally keyed objects never merge; conflicts fail unless --force; same-name groups split across the database and different languages' code (a table gl beside a Perl package LedgerSMB::GL) are not conflicts |
compile |
resolved KIR | CKM (ckm/model.json.zst) |
derives concentration risks and ConflictingEvidence; pass output cached by version + inputs; a live catalog keeps only its newest read |
commit |
CKM | ledger entries, indexes; integrity index | then the post-commit steps below |
Passes
A CompilerPass declares a name, dependencies, a version string and cache inputs. The PassManager orders passes by dependency and skips a pass whose version and inputs are unchanged — the skipping pass (cached) log line. Bump a pass's version when its behaviour changes, otherwise stale output is reused.
Analyzers
| Analyzer | Source |
|---|---|
sql_analyzer, sql_transform_analyzer |
DDL (statement by statement when a whole file fails to parse); SELECT/VIEW/procedures into the Transformation IR |
view_analyzer, plpgsql_analyzer, plsql_analyzer, trigger_analyzer |
views, PL/pgSQL and PL/SQL routines with per-statement reads/writes/calls, triggers |
schema_history |
dated migration scripts → change sets and classified changes |
oracle_catalog_analyzer |
live Oracle, PostgreSQL and ClickHouse catalogs → origin: live objects |
pentaho_analyzer |
.ktr / .kjb |
rust_analyzer, python_analyzer, javascript_analyzer, elixir_analyzer, perl_analyzer |
real AST parsing, symbols and Calls |
java_analyzer |
Java types and methods, embedded SQL, the iDempiere/ADempiere application model |
dbt_analyzer |
dbt models and schema.yml / sources.yml |
git_analyzer, github_analyzer, confluence_analyzer |
history and ticket ids, issues, wiki |
local_docs_analyzer, document_semantics_analyzer |
documents; optional LLM semantics |
crate_topology_analyzer, cicd_analyzer, dependency_analyzer, crypto_analyzer |
structure and dependencies |
Post-commit steps
These run after the ledger is written and are not compiler passes. In order:
- subsystem rollups;
- data-lineage linking (transformation steps to tables);
- routine linking (routines to the tables they read and write and the routines they call) and schema changes to the tables they alter;
[semantics]business-semantics synthesis (opt-in, RFC 0170);[conflicts](on by default): label mismatches, the code compared with the live database, and the list of current conflicts;- write behaviour per table, and tickets linked to what cites them;
[xref]: the cross-reference integrity index, written to a file, never to the ledger;[llm-description](opt-in), then extension steps, then[embeddings]vectors (opt-in).
Run logs
Every pipeline command, and every command that changes something, writes a JSON-lines run log (to EKOS_RUN_LOG or the state directory's runs/): one line per step with its counts, warnings redacted, and a last llm line with the number of model calls the run made. On the iDempiere testbed, all five pipeline commands logged a model-call count of 0. The console stores one log per run and shows it as a steps table.
Determinism
Same inputs, same outputs. Ids are derived, not random, where identity matters: relationship and evidence ids are derived from their content, so a re-run over unchanged input writes no new versions. Extensions that change observer output bump logic_version so the build cache invalidates.